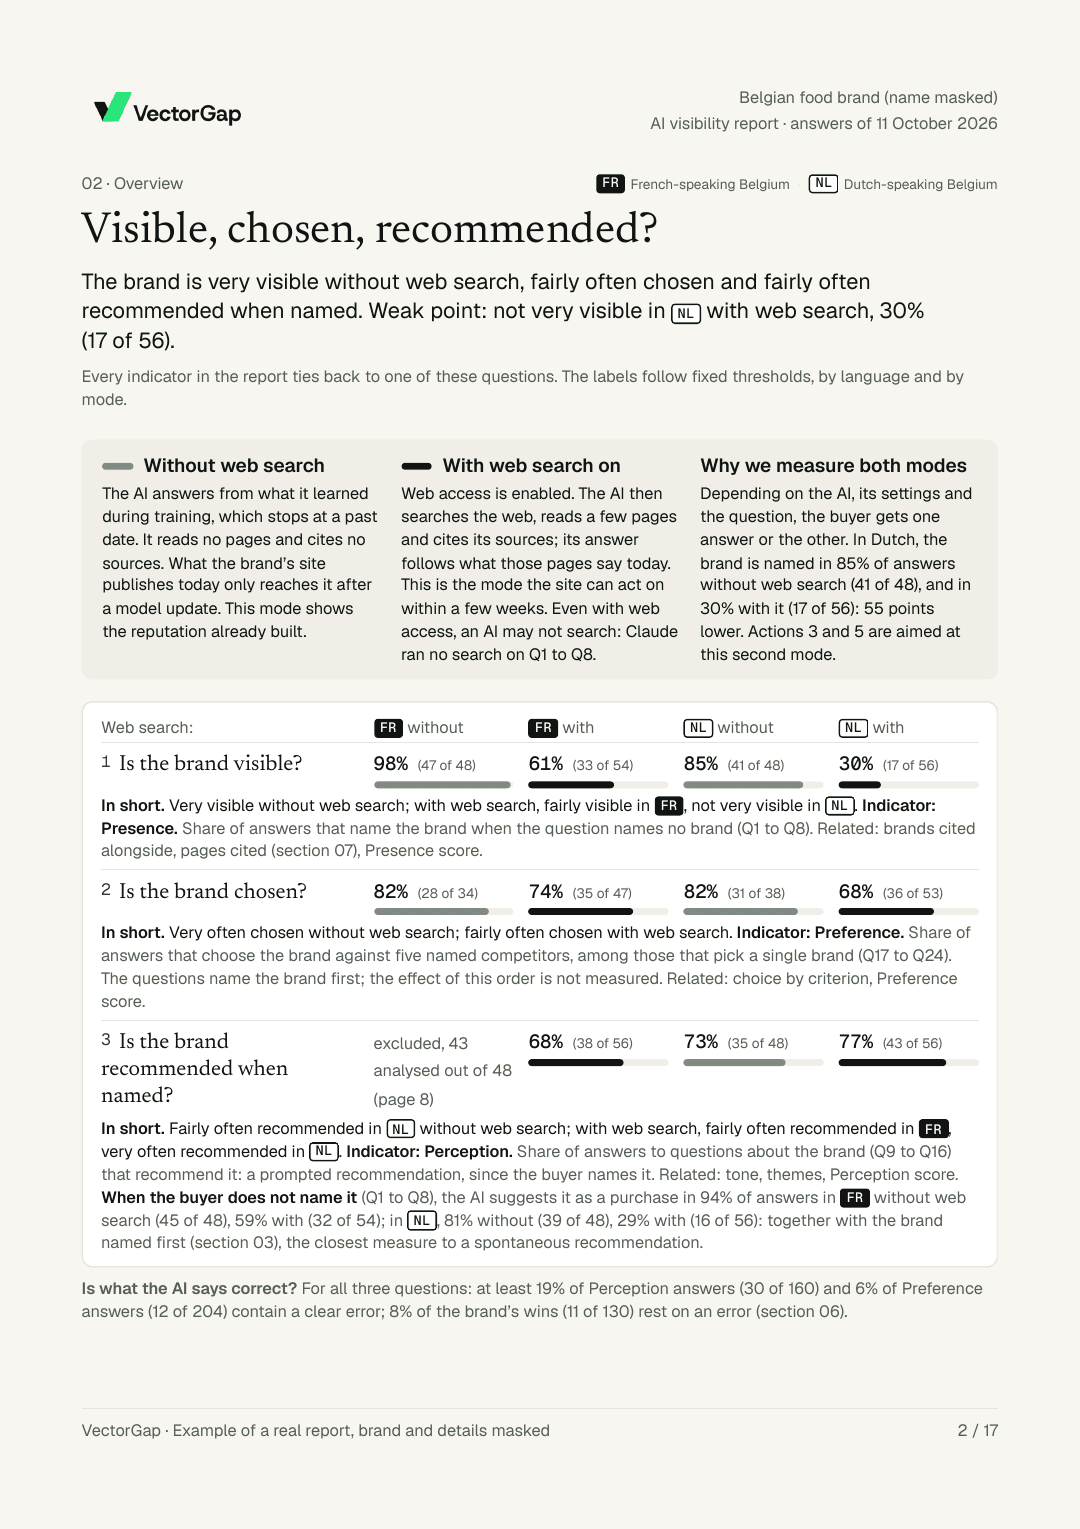
Without web search
What the AI learned
The AI answers with what it learned during its training. It changes when the model changes.
How we measure
Buyer questions, seven AIs, two modes and two runs. Every figure comes with the answers behind it.
The protocol
8 questions for each angle. Each question goes to 7 AIs with web search: ChatGPT, Claude, Gemini, Perplexity, Grok, Muse Spark from Meta, Google AI Mode. 5 of them also answer without web search. That makes 288 answers. The Presence questions are asked a second time: 96 more answers. Perplexity and Google AI Mode are measured with web search only.
Two modes
Without web search
The AI answers with what it learned during its training. It changes when the model changes.
With web search
The AI searches the web before it answers. It can change as soon as your pages change.
The two modes are shown side by side. They are never added into one number.
Two runs
Two identical measurements on the same day do not give identical answers. So at every measurement, VectorGap asks the Presence questions a second time. The figure covers both runs. The difference between the runs gives the margin of your own market.
The answers that differ between the two passes give each measurement its own margin. In the 30-day proof loop, a change counts only beyond that margin. It counts only for a business mentioned at least 5 times per pass, on average, on one of the two dates.
Chance test measured on 14 November 2026 on 7 companies (480 answers compared). A measurement run in a single pass keeps the previous rule: up to 6 answers out of 56, measured on 8 October 2026 in Montréal.
Read the full test in the article “How AIs interpret a brand”
Seven AIs
Which AI you ask explains 27% of the citation gaps. That is as much as the brand itself. The wording of the question explains 10%. A brand that measures one AI sees nothing of the six others.
The proof
Each finding carries the question, the AI and its version, the date, the mode and the answer. You can check any line against what the AI wrote.
Before and after
When I compare two dates, a difference counts only when it is larger than the margin measured on your market. The questions, the AIs and the mode stay identical.
Start
$250, once. Two markets, measured now and measured again in 30 days. If the report teaches you nothing, I refund it.
By ordering, you accept the Snapshot terms.